Tutorial: Spiral Fitting
Last updated: September 16, 2026
Most of our segmentation tools work bottom-up. GrowPatch, lasagna, and manual segmentation in VC3D all produce patches — pieces of papyrus surface that you grow bigger and bigger until they hit a tricky region and stall. Other tools trace individual fibers. Either way you end up with a big pile of small pieces: segments, fibers, point annotations. What we really want is the whole scroll — one surface covering every winding of the original papyrus sheet, from the center to the outer shell. However, gluing the pieces together directly is hard, especially where there are gaps between them. 1
That is what the spiral fit does. It takes the whole pile of partial evidence — surface patches, traced lines, winding annotations, volumetric predictions — and fits a single, globally coherent surface for the entire scroll that agrees with as much of that evidence as possible. Where the evidence is dense, the fitted surface follows it closely; where there are gaps, the spiral bridges them smoothly instead of stopping or leaving a gap.
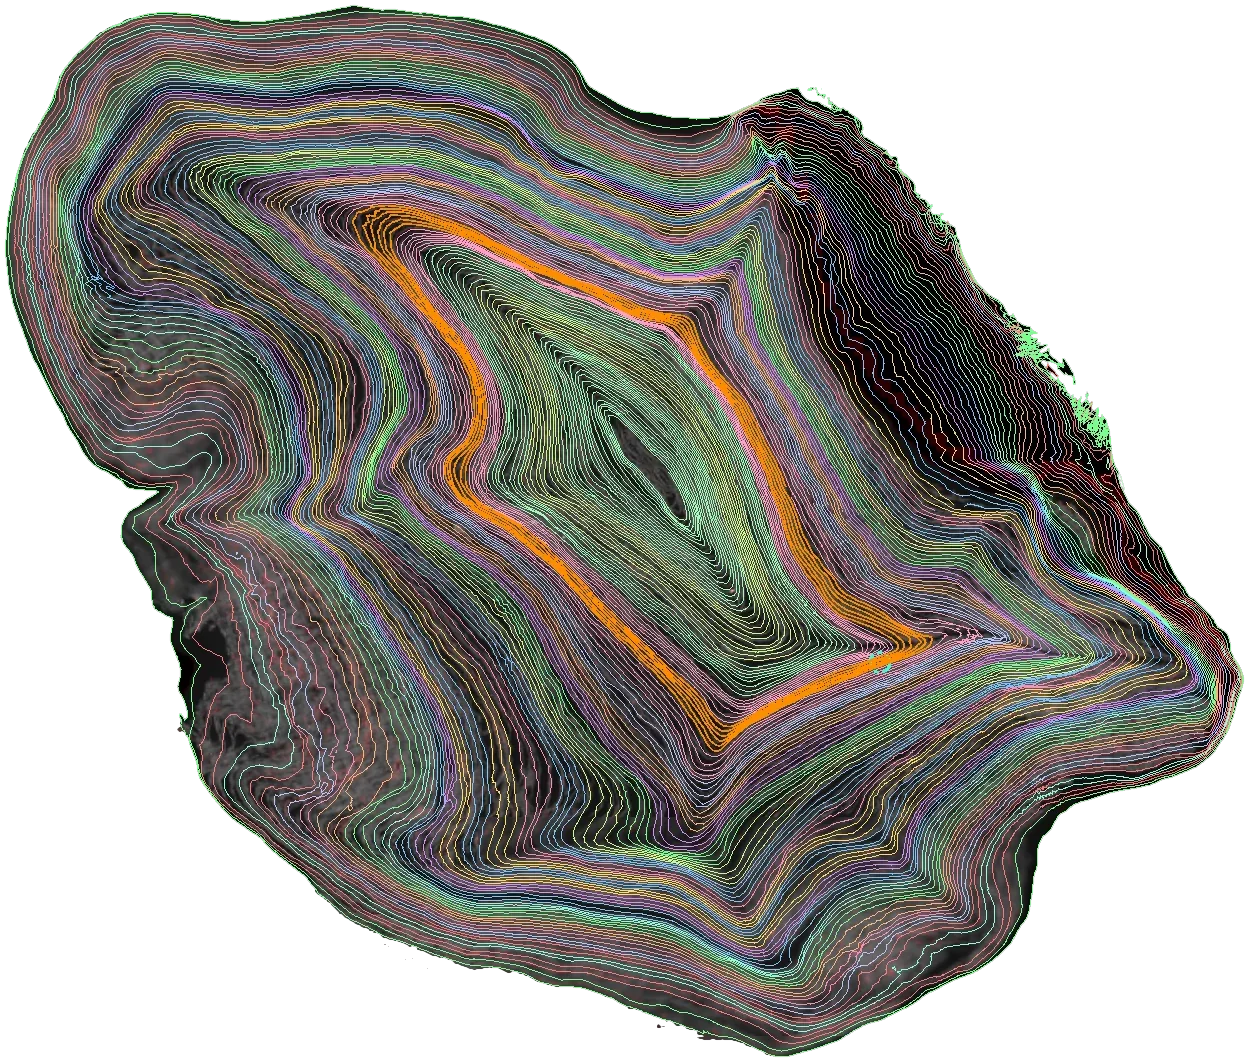
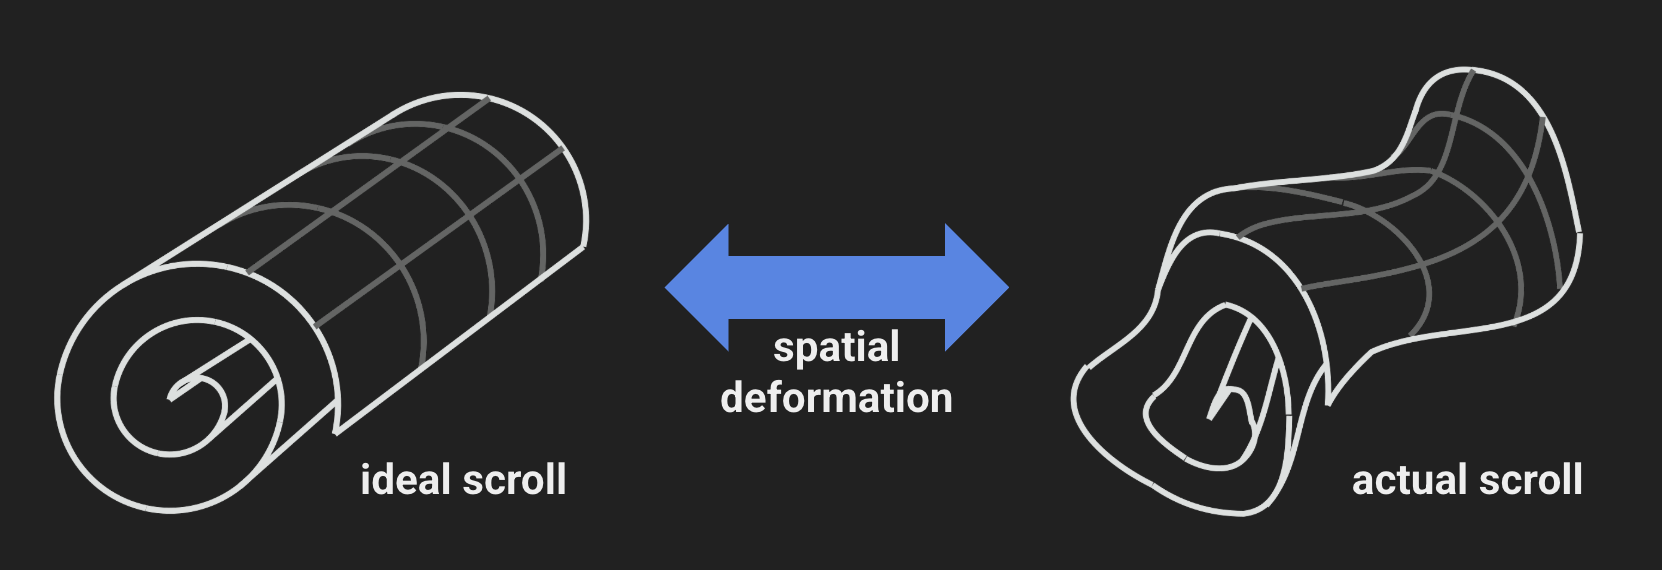
The core idea: we know the scroll was originally one long rectangular sheet, rolled up into a neat spiral. The eruption of Vesuvius deformed that spiral into the crushed shape we see in the CT scan. Instead of reconstructing the surface piece by piece, we search for the combination of ideal scroll shape and smooth deformation that best explains everything we observe. Once we have those, virtual unrolling comes almost for free: any point in the scan can be mapped back onto the original flat sheet.
The last section of this tutorial goes into how it works internally; first, the practical part — what goes in, what comes out, and how to run it.
What goes in
The spiral is flexible about its inputs: it consumes many kinds of evidence, in almost any combination, and each kind can be created manually or automatically.
- Surface patches — small pieces of scroll surface, stored as
tifxyzmeshes (the grid-of-3D-points format used by VC3D). These can come from GrowPatch, lasagna (direct growth, or growth around fibers), neural Copy In/Out, or any other segmentation method. Only human-checked (verified) patches are recommended; they are also used to calculate evaluation metrics. - Strips and lines of points that follow the surface of a single sheet — either point collections drawn in VC3D, or fibers traced in VC3D.
- Relative winding annotations — sets of points lying on different windings, annotated with how many windings apart they are (e.g. "these two points are exactly one wrap apart"). Represented as VC3D point collections with relative-winding annotations.
- Absolute winding annotations — points annotated with the absolute winding number they lie on (e.g. "this patch is on winding 20"). Also VC3D point collections.
- Coarser volumetric guidance derived from machine-learning predictions: predicted surface normals (from lasagna, stored as zarr volumes), predicted gradient magnitude (which captures the local radial density of windings), and skeletonised surface-prediction tracks (created with
extract_surface_tracks.py). - Scroll-level structure: the umbilicus (the scroll's central axis, as a function of z — required), and optionally a mesh of the scroll's outermost surface, which pins down where the spiral must end.
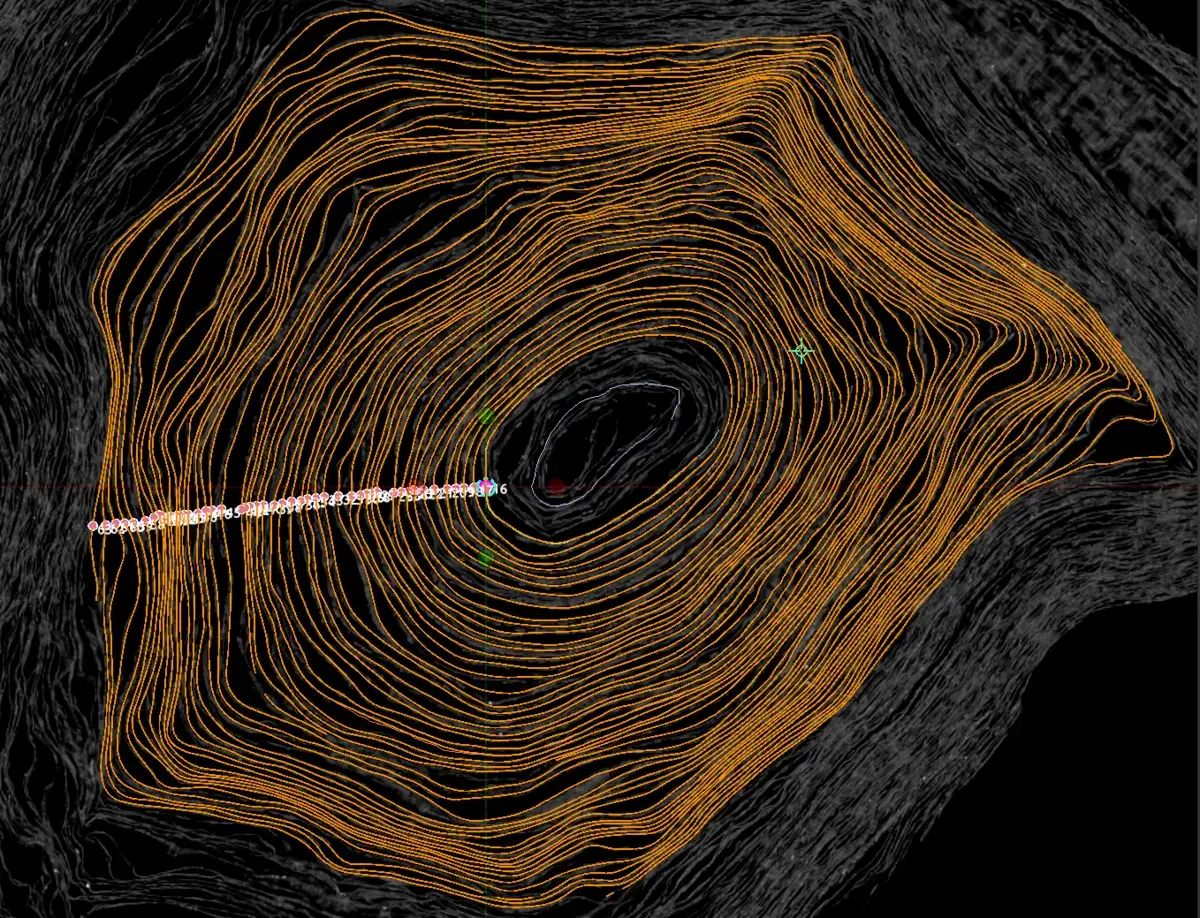
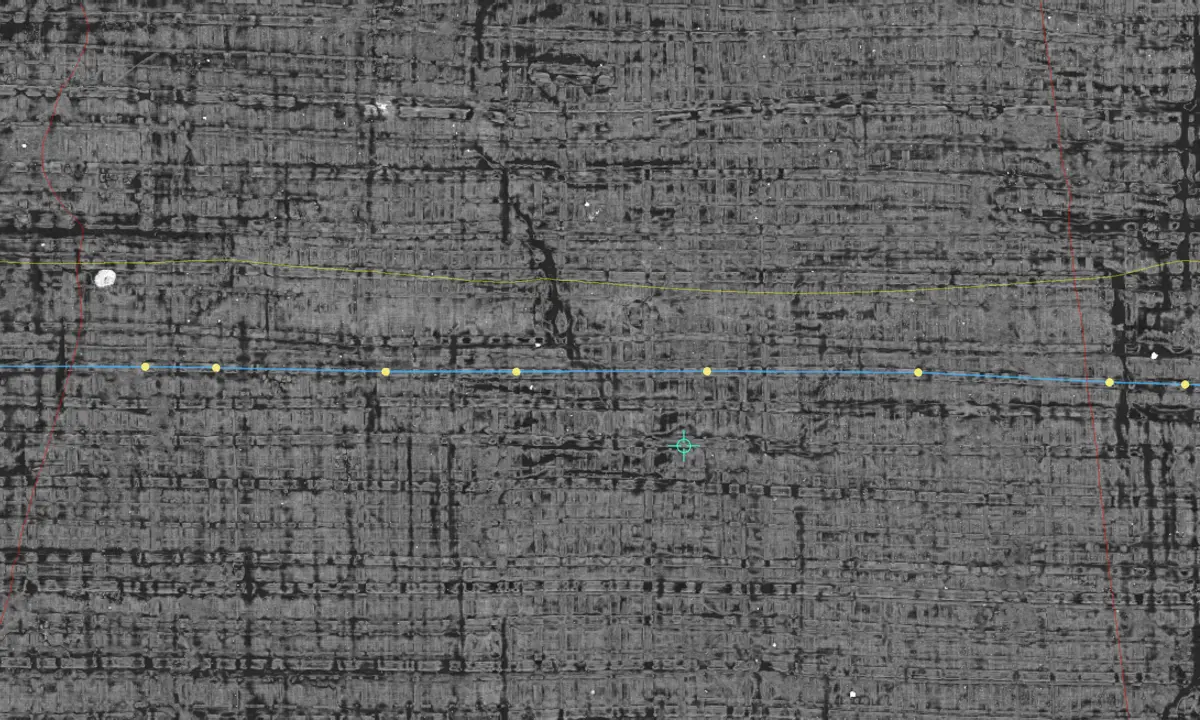
None of these individually needs to cover the scroll. Sparse, scattered evidence — a patch in one region, a fiber in another, a few relative-winding annotations in an ambiguous area — is combined by the fit into one consistent global solution, and annotations placed where the scroll is most damaged contribute the most.
What comes out
The output is one tifxyz mesh per winding of the scroll — a full set of surfaces that conform to the input constraints, covering the whole fitted region including places no patch ever reached. Two variants are written for each winding: wNNN, the pure fitted spiral surface, and wNNN_spliced, where the geometry of verified patches is spliced into the fitted surface wherever the fit and the patch agree — more locally accurate wherever trusted geometry exists.
Since these are ordinary tifxyz meshes, everything downstream works as usual: you can load them in VC3D, flatten them, and render surface volumes for ink detection. The repo also includes a tool (render_ink.py) that concatenates the windings into fixed-width chunks, flattens them, and renders ink predictions as a series of horizontal strips — more on that below.
Alongside the meshes, a fit writes a model checkpoint, satisfaction metrics — per-input-type statistics of how much of the evidence the final surface actually honors — and, optionally, overlay images showing the fitted windings drawn over scan slices.
How to run it
The code lives in the villa repository under spiral-fitting; the main entry point is fit_spiral.py. You'll need Python ≥ 3.14 and an NVIDIA GPU.
git clone https://github.com/ScrollPrize/villa.git
cd villa/spiral-fitting
uv sync
Everything the fit needs is declared in the project's own pyproject.toml, torch included — on Linux it comes from the CUDA 12.8 wheel index, so there is no separate torch install to get right. uv sync also builds vc_spiral, a small C++ extension the fit uses to link point annotations to patch surfaces, so the machine needs cmake and a C++ toolchain; you no longer need a volume-cartographer Python install.
On Windows, uv sync also installs triton-windows, a community build of Triton, because PyTorch publishes no triton wheel there and the fit's fused kernels need one. The first run compiles those kernels once.
If you do not install through the pyproject.toml, ensure your torch version is <2.13 versions >= 2.13 will require significantly more vram due to internal torch changes
Get the dataset
Ready-made inputs are published in the spiral-input dataset, which lives on the dl.ash2txt.org data server : Spiral Datasets (~90 GB):
rclone copy :http: ./spiral_datasets/phercparis4 \
    --http-url https://dl.ash2txt.org/datasets/spiral_datasets/PHercParis4/ \
    --transfers 32 -P
Note that re-running rclone resumes interrupted downloads. For PHerc Paris 4, the dataset contains verified and unverified patches, tracks, fibers, the outer shell, winding annotation JSONs, the umbilicus, and the volume inputs — see the dataset README for the exact layout.
Generating missing inputs
The published dataset ships ready-made inputs, but for a new scroll — or a new region of one — some of them may not exist yet. This section covers the four machine-generated inputs that most often need to be built from scratch: tracks, graph patches, fiber directions, and winding inference. Build them in roughly that order: graph patches are grown from tracks, and winding inference needs an existing spiral fit to seed from.
Unless noted, commands run from villa/spiral-fitting inside its uv environment. Every input has to be in the fit's own voxel frame (the same frame as the umbilicus, patches and z_begin/z_end), and should cover at least the z range you plan to fit — inputs outside the fit window are dropped at load.
Tracks
Tracks are skeletonized 2D curves through a binarized surface prediction, cut on regularly spaced horizontal (h:) and vertical (vy:/vx:) slabs. They live in a stdlib dbm database under tracks/.
1. Get a surface prediction. Published surface predictions for each scroll are listed in the data browser (look for surface-prediction), e.g. the thresholded surface_m7 predictions under s3://vesuvius-challenge-open-data/<scroll>/representations/predictions/surfaces/. To make your own, run vesuvius.predict → vesuvius.blend_logits → vesuvius.finalize_outputs --mode binary --threshold (see the vesuvius inference docs). The extractor treats any value > 0 as surface, so the prediction must be thresholded, and it expects a 3D (Z, Y, X) array.
2. Extract the tracks:
.venv/bin/python extract_surface_tracks.py \
    --predictions /path/to/surface-prediction.zarr/0 \
    --out /path/to/dataset/tracks/<name>.dbm \
    --z-min 4000 --z-max 17000
With a supported NVIDIA GPU (Linux x86-64, compute capability ≥ 8.0) this uses a fast GPU backend — a 4000-slice range takes seconds on a few H100s — and otherwise falls back to a much slower CPU skeletonizer (--backend, --gpus to choose). It also writes the packed <name>.dbm.vctracks/ store the fit loads fastest. Runs resume: slabs already in the database are skipped.
3. Optionally, cache the track crossings (the fit otherwise computes them in memory):
.venv/bin/python build_track_crossings.py /path/to/dataset/tracks/<name>.dbm
If the database isn't named tracks/2um_ds2_ps256_surf_v2.dbm, or there is more than one in tracks/, set "paths": {"tracks_dbm": "tracks/<name>.dbm"} in spiral-scroll.json. Tracks are off by default; enable them with input_use_tracks (see the fit configuration). The spiral-fitting README has GPU requirements and timings.
Graph patches
Graph patches are tifxyz patches grown automatically from the tracks by grow_track_graph.py: starting from a seed track, it grows a sheet across track crossings, accepting a step only where enough crossing tracks agree. They need both track sidecars from above — the .vctracks store and the .crossings.npz cache — built from the same database:
.venv/bin/python grow_track_graph.py \
    /path/to/dataset/tracks/<name>.dbm.vctracks \
    /path/to/dataset/tracks/<name>.dbm.crossings.npz \
    /path/to/dataset/graph_patches \
    --random-count 1000 --workers 16
--random-count N grows N patches from random long seed tracks (or pass explicit track rows with --seeds). Re-running into the same folder adds new patches and skips seeds already used. The same tool is available in VC3D under Actions → Grow Track Patches..., which runs the script for you and loads the results.
Graph patches are machine-generated, not human-checked, but the fit has no separate input for them: they are read through the patches input, exactly like verified patches. Point the Verified patches path (paths.verified_patches) at the graph_patches/ folder, or at a folder containing both sets.
Fiber directions
fiber_directions.npz holds sampled fiber orientations from a 3D fiber prediction. The loss only asks that the fitted sheet lie along the local fiber direction; it doesn't tie samples to a particular winding.
From an existing fiber prediction. Fiber predictions for several scrolls are already published on the open-data bucket, under <scroll>/representations/predictions/fibers/ (listed in the data browser). Each prediction folder contains a .lasagna.json manifest, which is all the extractor needs. For PHerc. Paris 4:
aws s3 ls --no-sign-request \
    s3://vesuvius-challenge-open-data/PHercParis4/representations/predictions/fibers/20260411134726-fibers-20260801084232-L1/
Pass the manifest's HTTPS URL to fiber_direction_samples.py, from villa/spiral-fitting. It downloads only the chunks that intersect the z range and writes the samples into the dataset:
.venv/bin/python fiber_direction_samples.py \
    https://vesuvius-challenge-open-data.s3.us-east-1.amazonaws.com/PHercParis4/representations/predictions/fibers/20260411134726-fibers-20260801084232-L1/PHercParis4-20260411134726-las-sd1-d74cca79.lasagna.json \
    /path/to/dataset/fiber_directions.npz \
    --z-roi 4000,17000 --output-scale 4 \
    --presence-threshold 160 --cell-size 2
The manifest must be reachable over HTTP(S); a local path won't work. --z-roi is half-open and in fit coordinates, and --output-scale is the number of full-resolution scan voxels per fit voxel (4 for a fit at pyramid level /2, as for PHerc. Paris 4). Getting either wrong silently misplaces the samples, or leaves none inside the fit window. The fiber loss is off by default: set input_use_fiber_directions to true and loss_weight_fiber_directions above 0.
If no fiber prediction exists, run inference with the scrollprize/lasagna-fiber model. It writes presence, nx and ny channels plus a .lasagna.json manifest, and runs from the lasagna environment:
cd villa/lasagna
python3 scripts/bootstrap_venv.py --venv .venv --backend cu128
source .venv/bin/activate

hf download scrollprize/lasagna-fiber \
    s1a_128_1_single_8x8_20260801_084232_best91_5k.pt --local-dir models/lasagna-fiber

python -m vesuvius.neural_tracing.fiber_trace_3d.infer \
    --input /path/to/volume.zarr/1 \
    --output /path/to/predictions/fiber.lasagna.json \
    --checkpoint models/lasagna-fiber/s1a_128_1_single_8x8_20260801_084232_best91_5k.pt \
    --devices all --tile-size 512 --overlap 96 --border 32 \
    --inference-scaledown-power 2
The repository holds two variants, and each must be paired with the input pyramid level it was trained on: the SD1 checkpoint above takes group 1 of a 2.4 µm scan, while the SD2 checkpoint (s1a_128_2_single_..._best_25_9k.pt) takes group 2. On a ~9 µm scan, use the SD2 checkpoint on group 0. The model card has the details, including how to fetch input volumes with lasagna-download.
Then serve the prediction folder over HTTP (e.g. python3 -m http.server in /path/to/predictions, or upload it to a bucket) and run fiber_direction_samples.py on its manifest URL exactly as above.
Winding inference
winding_inference/ is a compact store of winding crossings predicted by a neural winding model along rays through the scroll. It drives the default dense-spacing mode (dense_spacing_mode: "winding_model"), so a dataset without it fails validation under the default settings. To fit without it, set "dense_spacing_mode": "grad_mag" (which uses the gradient-magnitude volume instead) or "input_use_winding_inference": false.
Generating it takes a winding model and an existing spiral fit, since the rays are seeded on that fit's windings — so a first fit in grad_mag mode is the usual starting point. A trained model is published as scrollprize/winding_model_9um:
hf download scrollprize/winding_model_9um ckpt_final.pth config.json --local-dir models/winding_model_9um
It was trained on ~9.6 µm volumes (2.4 µm scans at pyramid level 2) from PHerc. 0139, PHerc. 1667 and PHerc. Paris 4, so run it on a volume at roughly that resolution. The tools live in vesuvius/src/vesuvius/neural_tracing/winding_models and run from a vesuvius environment.
1. Run the winding model along the fit, writing a native phase cache:
python infer_winding_volume.py \
    /path/to/run/checkpoint_fitted.ckpt winding_native_phase.zarr \
    --model-ckpt models/winding_model_9um/ckpt_final.pth \
    --reference-zarr /path/to/volume.zarr --volume-scale 0 \
    --z-range 4000 17000 --winding-step 3 --seed-spacing 60 \
    --gpus 0,1 --native-phase-only
The reference zarr's scale-0 grid defines the output coordinates, so use the volume the fit runs on. --z-range and --winding-range default to the fitted checkpoint's ranges. It also needs the scroll's umbilicus.json (--umbilicus, or found from the checkpoint's dataset). The cache is large — about 150 GB for all of PHerc. Paris 4.
2. Export the compact store into the dataset:
python export_spiral_supervision.py winding_native_phase.zarr \
    /path/to/dataset/winding_inference --workers 32
The export is restartable, refuses to overwrite an existing store, and --validate /path/to/dataset/winding_inference checks a finished one. NATIVE_PHASE_CACHE.md documents both steps and the store format. To train your own winding model, run train_winding_model.py <config.json> on volumes paired with existing segments or spiral fits; the published model's config.json is a working example.
Configure
Two separate things configure a run: where the data is — given on the command line, plus one file inside the dataset — and how to fit it, a flat set of named settings.
The dataset
fit_spiral.py takes a --dataset root and resolves the conventional layout underneath it: umbilicus.json, verified_patches/, fibers/, fiber_directions.npz, outer_shell/, tracks/, winding_inference/, the lasagna_inputs/*.ome.zarr volumes, and the point-collection documents abs_winding.json, relative_windings.json, same_windings.json and drawn_control_points.json. A download of the published dataset is already in that layout, so there are no paths to edit.
You also need to provide a spiral-scroll.json in the dataset root, recording the physical facts of the scroll:
{
  "schema_version": 1,
  "name": "PHercParis4",
  "voxel_size_um": 9.6,
  "spiral_outward_sense": "CW"
}
name is free-form and is what appears in the generated run-folder name. spiral_outward_sense ("CW" or "ACW") says which way the spiral turns as it winds outward. No automated method determines it: it is read off the CT data by a person in VC3D, or taken from an already-fitted spiral. The file can also carry a paths object naming individual inputs whose filenames don't match the conventional ones ("tracks_dbm" is the usual one), and normal_zarr_group / lasagna_scale, which choose the OME-Zarr pyramid level the lasagna normal stores are read at — these are easy to get wrong silently, so read the scale off the store's own .zattrs rather than copying another scroll's values. The spiral-fitting README documents the full schema.
Running the fit
There are two ways to run the spiral fitting, either through the CLI or through an interactive fit session in the VC3D spiral workspace. Both run the same fit_spiral.py script. They differ in two ways:
- The VC3D workspace can be configured to render a flatten view at an interval or on the fits completion
- The VC3D workspace supports adding inputs to "live" fits, interactively
- VC3D Workspace
- CLI
Starting a fit session
Open VC3D, select the scroll's volume package in VC3D, then select the Spiral workspace tab. It uses the same scan as the main workspace, with a flattened preview and CT slice views beside it. If you are planning on running the spiral service on the machine you're opening VC3D with , ensure you have the venv activated in the terminal before opening VC3D.
The spiral workspace runs through a service whether you're using it on the machine you're viewing VC3D through or over a network connection (internet or local LAN).
Navigating the UI
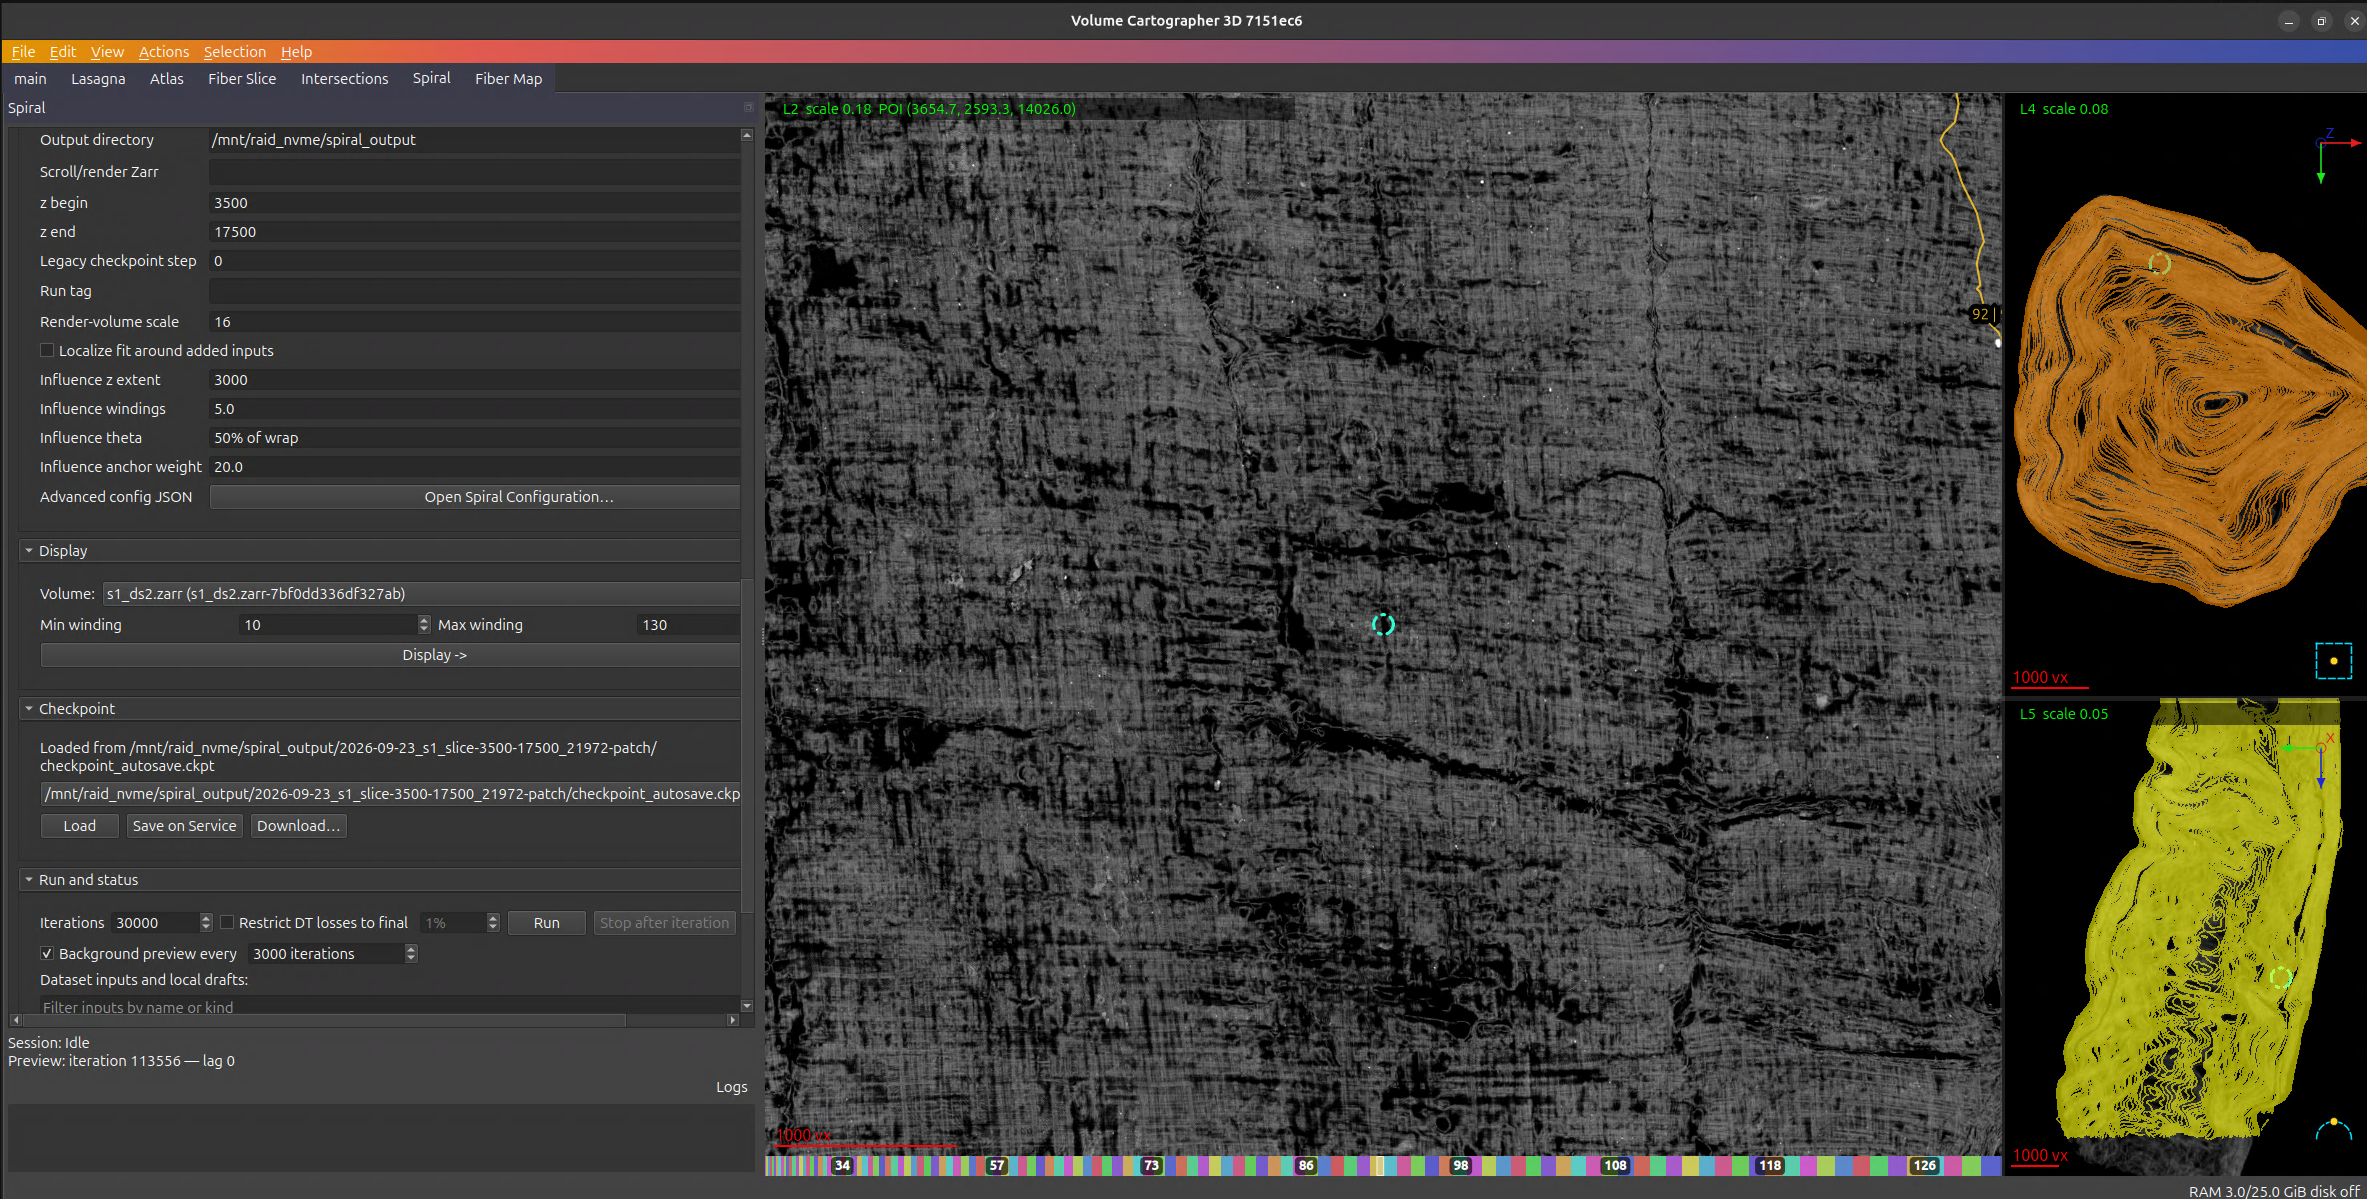
The spiral workspace is composed of two "windows": the configuration dock, on the left-side of the UI, and the flattened spiral view, which occupies the majority of the view. When no fit has returned a "preview", the flattened view is just a black rectangle.
The configuration dock for the most part should be used top-to-bottom, and all fits begin with a session "connection"
Connecting to a session
In Spiral Service, choose a connection:
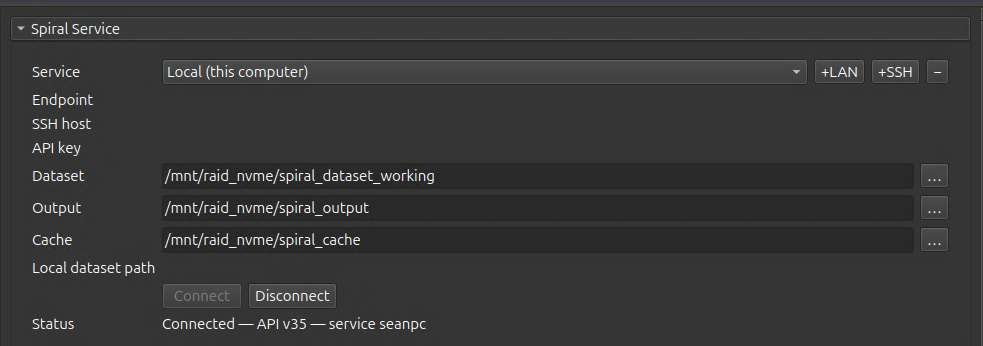
- Local: set Dataset and Output, then Connect. VC3D launches the service locally; its Python environment must have the spiral-fitting dependencies installed. Keep Output outside the dataset directory.
- Remote (SSH): start the service on the GPU machine using the command below, then click +SSH in VC3D. Enter
[user@]host(an SSH-config alias also works) and port8765, then Connect. Use SSH keys or an agent; if the host is new, connect once withssh user@hostin a terminal to accept its host key. VC3D creates the tunnel and retrieves the API key automatically. - Remote (LAN): start the same service with
--bind 0.0.0.0, then click +LAN. Set Endpoint tohttp://HOST:8765and paste the API key printed by the service. Direct HTTP is unencrypted; use it on a trusted network, or use SSH.
For either remote connection, run this on the GPU host from villa/spiral-fitting with dependencies installed (add --bind 0.0.0.0 for LAN):
uv run python spiral_service.py --port 8765 \
    --dataset /data/scrolls/s1 --output /data/spiral-output/s1 \
    --gpus 0 --session-name my-fit
Keep this process running in a persistent terminal such as tmux. Remote fits continue when VC3D disconnects. Previews and checkpoints transfer automatically; a shared filesystem is unnecessary. If you mount the remote dataset locally, set Local dataset path to its matching root to enable verified patch overlays.
Configuring and running the initial fit
The default parameters used by fit_spiral.py also apply to fit sessions run through the workspace. The only fields necessary for you to fill in are Output Directory, z begin and z end. If you'd like to override the defaults, click Open Spiral Configuration... and edit the fields. Hovering the mouse over the text for each field will show a brief description of what it does.
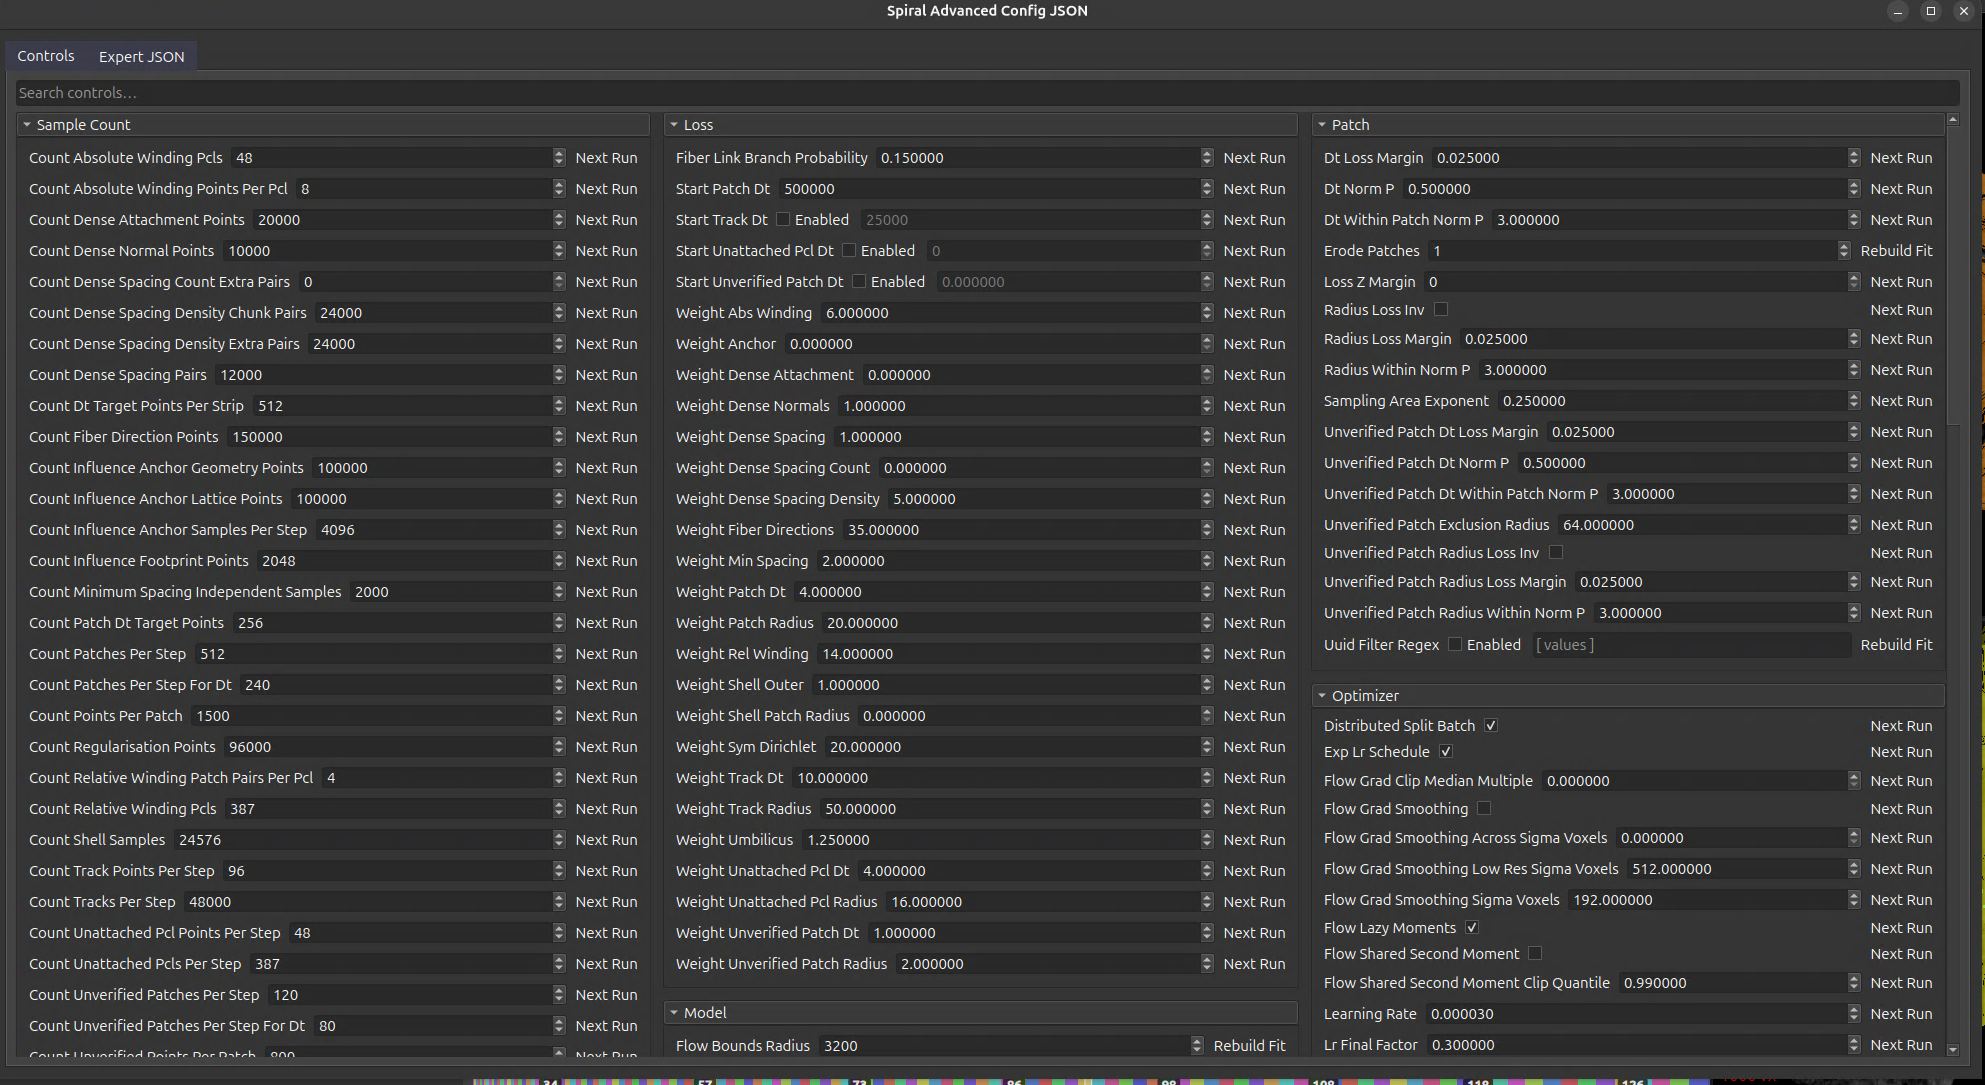
Set z begin / z end in Fit and output; start with a small range. Click Initialize Fit, choose Iterations, then Run. Stop after iteration pauses at the next completed step; another Run continues the fit. Initialization becomes Rebuild Fit once a fit exists. To resume a saved model, select it under Checkpoint and click Load.
Once the configured number of steps completes, or on the interval set by Background preview every.. spinbox when enabled, a flattened spiral surface will display in the viewer.
Navigation in the spiral preview surface and the volume views is similar to the rest of VC3D
right-click + dragto pan,- mouse-wheel to zoom,
- shift+wheel to move through slices on the flattened view,
Randctrl+cover a point to show that area in all views,Xrecenters the views on that focus if you have panned away
The spiral surface also contains a "minimap". Click the winding minimap below the flattened view to jump along the scroll. Use Min winding / Max winding limit the displayed windings (-1 means through the last).
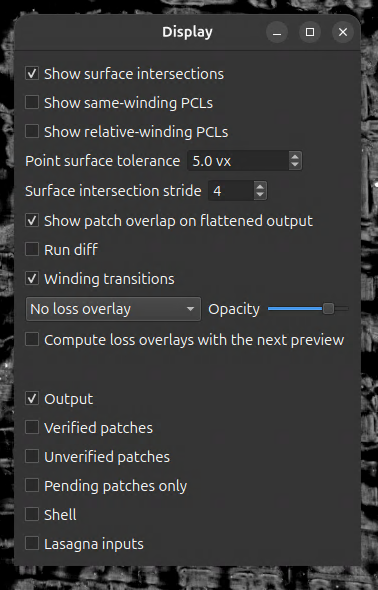
Within the display section of the configuration dock is the Volume combobox, which allows you to select the primary displayed volume (Overlays are managed like regular VC3D, via the Overlay toolbar item). The spiral preview surface also has many additional overlays available. Use Display → to toggle output, input patches, fibers and point collections, surface intersections, winding boundaries, patch overlap, and run differences. Loss overlays require Compute loss overlays with the next preview, which roughly doubles preview cost. The fixed status area shows fit progress and preview age; Logs opens service messages.
Annotate and apply changes
When fitting a spiral using the spiral workspace, you can add constraints to a running fit.
| Key or gesture | Action |
|---|---|
| Tap Ctrl | Toggle patch painting; left-drag paints, right-drag erases |
| Ctrl+wheel | Change brush size |
| Shift+right-drag | Draw a freehand control-point line |
| Ctrl + right-click -> 2d line annotation | place control points to use in the fiber annotation, press E to optimize and display the line annotation window |
| Hold V + left-clicks | Draw a control-point line through chosen points; release V to finish |
| Q, then left-clicks | Place points belonging to the same winding |
| E, then left-clicks | Place relative-winding points numbered 0, 1, 2, …; click successive windings in order |
| F | Reverse the active point collection and its relative-winding ordering |
| Escape | Exit the current drawing/point-placement mode |
| Shift+E | Prepare drawing drafts for submission |
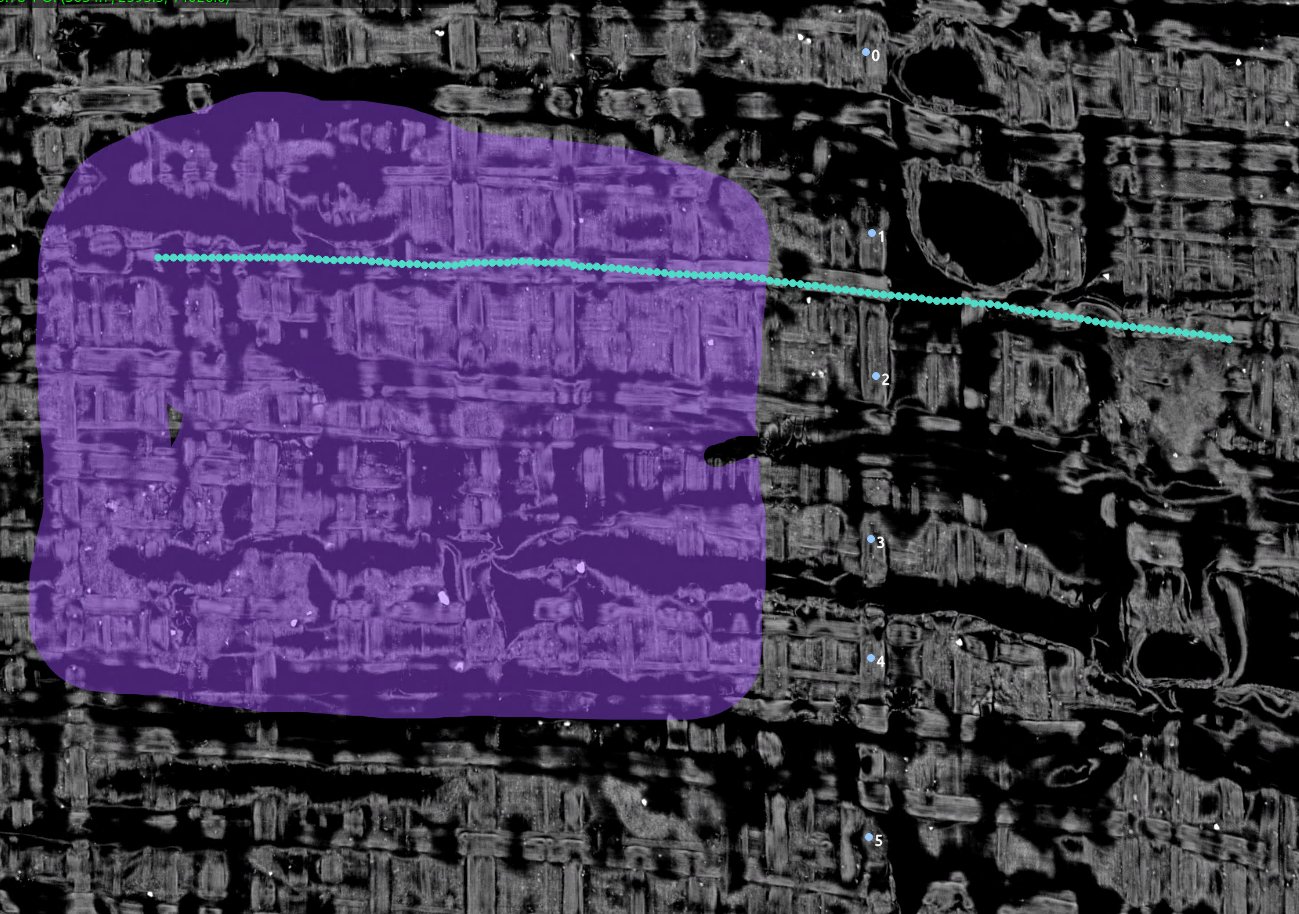
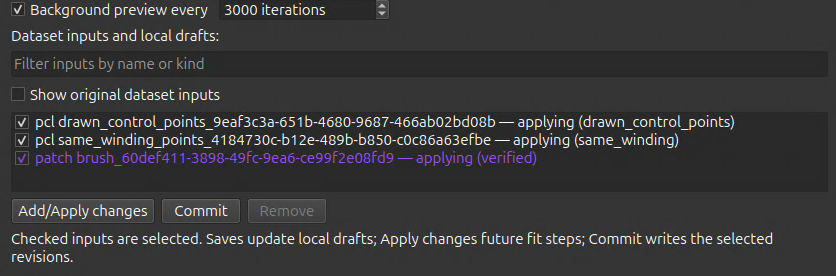
Use Add/Apply changes to submit ready drafts to the fit, including while it is running. Commit persists the selected changes into the dataset; applying alone does not. For existing inputs, enable Show original dataset inputs, then right-click an entry and choose Edit. Patch and fiber editors save working copies; use Add/Apply afterward. Remove stages a removal, Restore reverses it before Commit, and committing the removal deletes the managed dataset entry.
Preview intervals and rendering
Enable Background preview every and choose an interval in iterations before clicking Run (default interval: 100). The service captures the fit at an iteration boundary, exports its surface, and flattens it through Lasagna; fitting resumes while flattening continues. VC3D downloads the finished geometry and displays the scan on that surface. This is a geometry preview; ink strips are produced separately by Rendering ink.
A preview is also requested when a connected run finishes or is stopped. Exporting and flattening can take minutes, so the displayed preview may trail the fit; check its iteration and lag in the status area. Until a new preview succeeds, the previous one stays visible.
Where files live
Generated files live on the service machine, under its Output root; the example above uses /data/spiral-output/s1/my-fit/. This holds fit run directories, previews, uploads, and checkpoints, including checkpoint_autosave.ckpt. For local services, an empty Output field uses a per-dataset directory in VC3D's application-data folder; set it explicitly for an easy-to-find location. The derived cache defaults to ~/.cache/vc3d/spiral.
Checkpoint → Save on Service saves remotely; Download… copies a checkpoint to your computer. VC3D also caches downloaded display artifacts locally. Only Commit writes your annotation changes back into the dataset. See the service README for connection and storage details.
Improving the fit "interactively"
Once the spiral surface is shown in VC3D you can inspect it for mistakes. Mistakes can be grouped into a few types, and the "fixes" for these mistakes can come from many different kinds of constraints.
Sheet Switches are areas where the spiral fit has started on one winding, lets call it winding A, and departs from it and continues along an adjacent winding B. You can fix these by either telling the spiral fit "this point continues this way" (patches, fibers), or "these two points are not the same winding" (relative winding annotations). For the most part unless relative winding annotations fall on patches (and produce links), you get more "bang for your buck" with patches or fibers in resolving these types of errors
Wandering is when the spiral fit shifts back and forth along the normal of the surface, never adhering quite to the proper sheet and occasionally (but only briefly) falling onto an adjacent winding. These are best resolved with patches, but fibers could suffice if there is simply just a complete lack of annotation in this area.
When you identify one of these areas, and you've added your fix (in the form of some new constraint, see the keybinds above) to the live fit, it's typically good pratice to disable the "DT" losses temporarily. These losses have a tendency to make the spiral "stick" to an annotation, making it hard for it to adjust to your new annotations. The VC3D spiral workspace makes this easy, by checking the box Restrict DT losses to final... and entering a percentage. In this example, the fit will run for 2000 additional iterations (extending its polynomial LR decay to account for the longer horizon), with the first 75% of those iterations having its "DT" losses disabled.

The fit configuration
Everything else — the fitted z-range, which inputs participate, loss weights, resolutions, step counts — is a flat dictionary of named settings defined in config.py: one attribute of the Config class per knob, each with its default. You can pass overrides as JSON:
FIT_SPIRAL_CONFIG_OVERRIDES='{"z_begin": 10500, "z_end": 11500, "optimizer_num_training_steps": 10000}' \
    python fit_spiral.py --dataset ./spiral_datasets/phercparis4
The settings you are most likely to touch:
-
z_begin,z_end— the slice range (in full-resolution voxels) to fit; the defaults, 4,000 and 17,000, span the whole written region of Scroll 1. Consider starting with a small range: fitting all of it needs a lot of GPU memory and time, and a ~1,000-slice range is a good first run on a smaller GPU. Per-step sample counts are scaled automatically to the size of the z-range, so the other hyperparameters don't need retuning when you change it. -
input_use_*— whether an input that is present is actually used. Each optional input source has its own toggle, independent of whether its file is there:input_use_verified_patches,input_use_tracks,input_use_fibers,input_use_fiber_directions,input_use_normals,input_use_gradient_magnitude,input_use_winding_inference,input_use_outer_shell, plus one per annotation role —input_use_pcl_absolute,input_use_pcl_relative,input_use_pcl_same_winding,input_use_pcl_drawn_control_points.Note thatinput_use_tracksdefaults tofalse, so a dataset that includes a tracks DBM will not use it unless you turn it on:FIT_SPIRAL_CONFIG_OVERRIDES='{"input_use_tracks": true, ...}'A few ready-made override files live in
configs/.
A few environment variables control the run itself rather than the fit:
| Variable | Effect |
|---|---|
FIT_SPIRAL_CONFIG_OVERRIDES | JSON dict of Config overrides, e.g. '{"optimizer_num_training_steps": 10000}' |
FIT_SPIRAL_OUT_DIR | Parent directory for the generated run folder (default ./out) |
FIT_SPIRAL_RUN_DIR | Use this exact directory as the run folder, instead of generating a name |
FIT_SPIRAL_RUN_TAG | Tag appended to the output folder and mesh names |
FIT_SPIRAL_RESUME_PATH / FIT_SPIRAL_RESUME_STEP | Resume from a checkpoint |
WANDB_MODE | Set to online to log losses and visualizations to Weights & Biases (default disabled) |
The cache of preprocessed inputs — which speeds up subsequent runs a lot — defaults to ~/.cache/vc3d/spiral, shared across datasets since its entries are content-addressed; --cache DIR (or FIT_SPIRAL_CACHE_DIR) moves it elsewhere.
Fit
python fit_spiral.py --dataset ./spiral_datasets/phercparis4
That's it — the script loads the inputs (caching the expensive preprocessing), then runs 30,000 optimization steps, printing the loss breakdown every 200 steps. Multi-GPU is supported via torchrun --nproc-per-node=N fit_spiral.py --dataset ..., which splits each step's work across GPUs.
To run the whole pipeline in one command — fit, then render ink, then score it — use runners/run_single.py instead. It takes the same --dataset, plus an --ink-volume, and accepts the same configuration overrides as a --config JSON file; runners/run_sweep.py runs a whole folder of such configs concurrently across GPUs.
When it finishes, you get a self-contained run folder:
out/2026-07-08_s1_slice-10500-11500_27399-patch_<run-name>/
├── checkpoint_fitted.ckpt             # fitted model (resumable)
├── satisfied_fitted.json              # which individual inputs the fit honors
├── satisfaction_metrics_fitted.json   # and the summary of those, per input type
├── spiral_on_*_fitted.png             # fitted windings overlaid on inputs
└── meshes/mesh/
    ├── w010/                          # one tifxyz mesh per winding...
    ├── w010_spliced/                  # ...plus the patch-spliced variant
    ├── w011/
    └── ...
The overlay PNGs are only written when output_save_png_visualizations is on; it defaults to off, since rendering them means reading scan slices back at the end of the fit.
Tips for getting better spiral fits
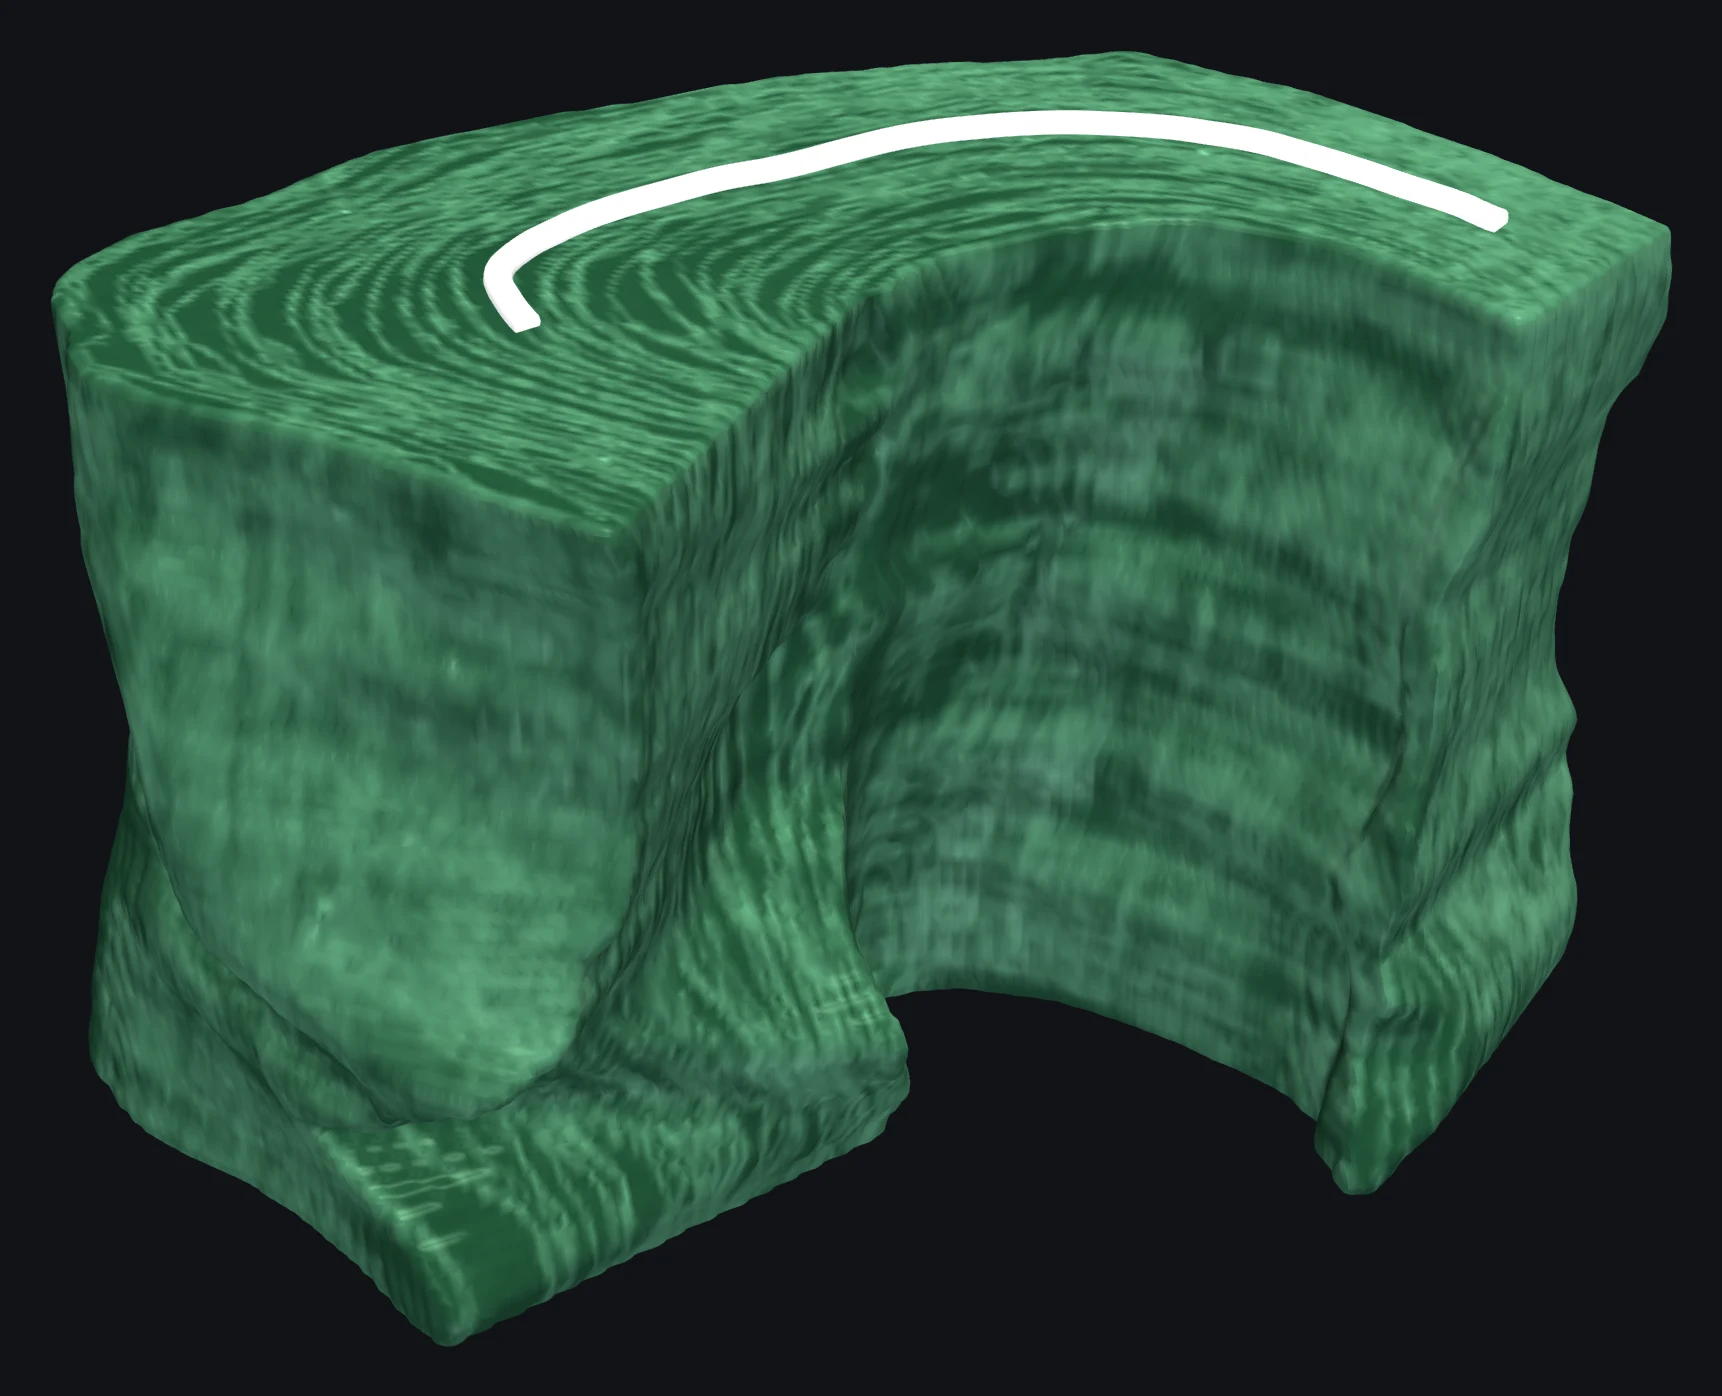
The goal of any spiral fit is to do as little annotation as possible . This is, of course, a hard question to answer until you have a perfect fit and work backwards. However, we can get a rough guess if we consider how the spiral interpolates. The easiest way to think of this is to imagine the scroll as a set of local shapes glued together, perhaps one section of the scroll looks like a C or one a J or god forbid a Z. In each of these shaped sections, we need something to inform the spiral how the local area should be deformed.
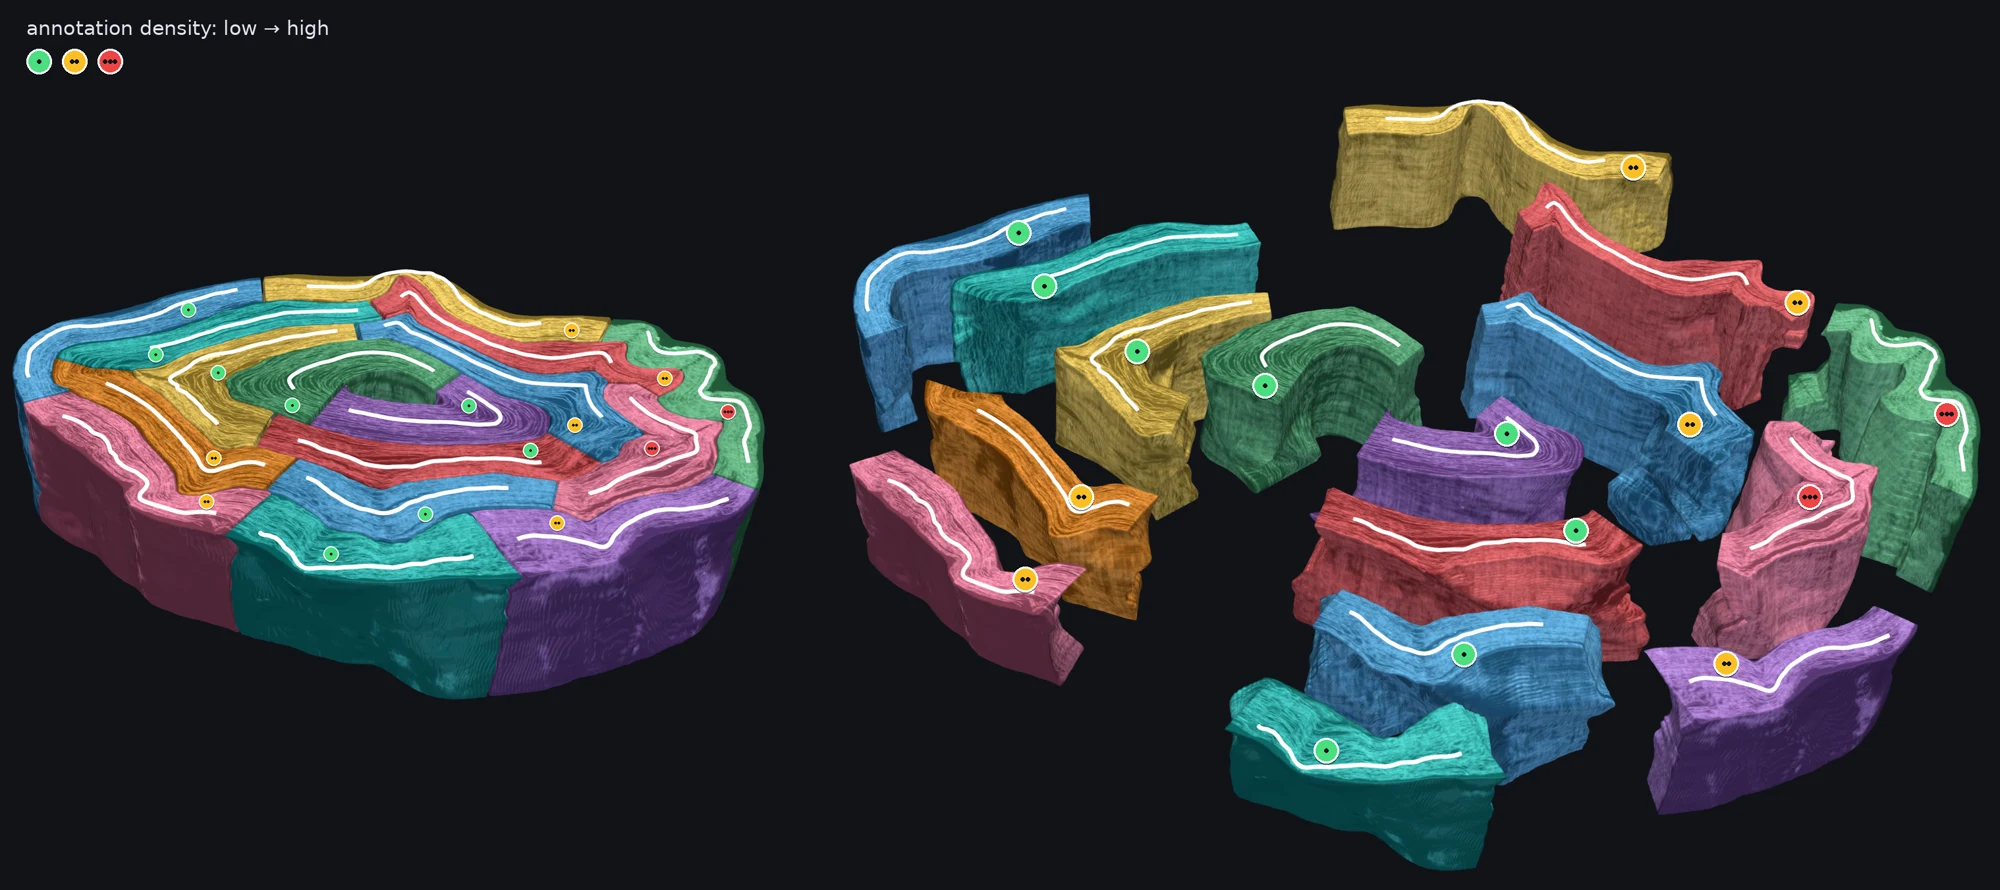
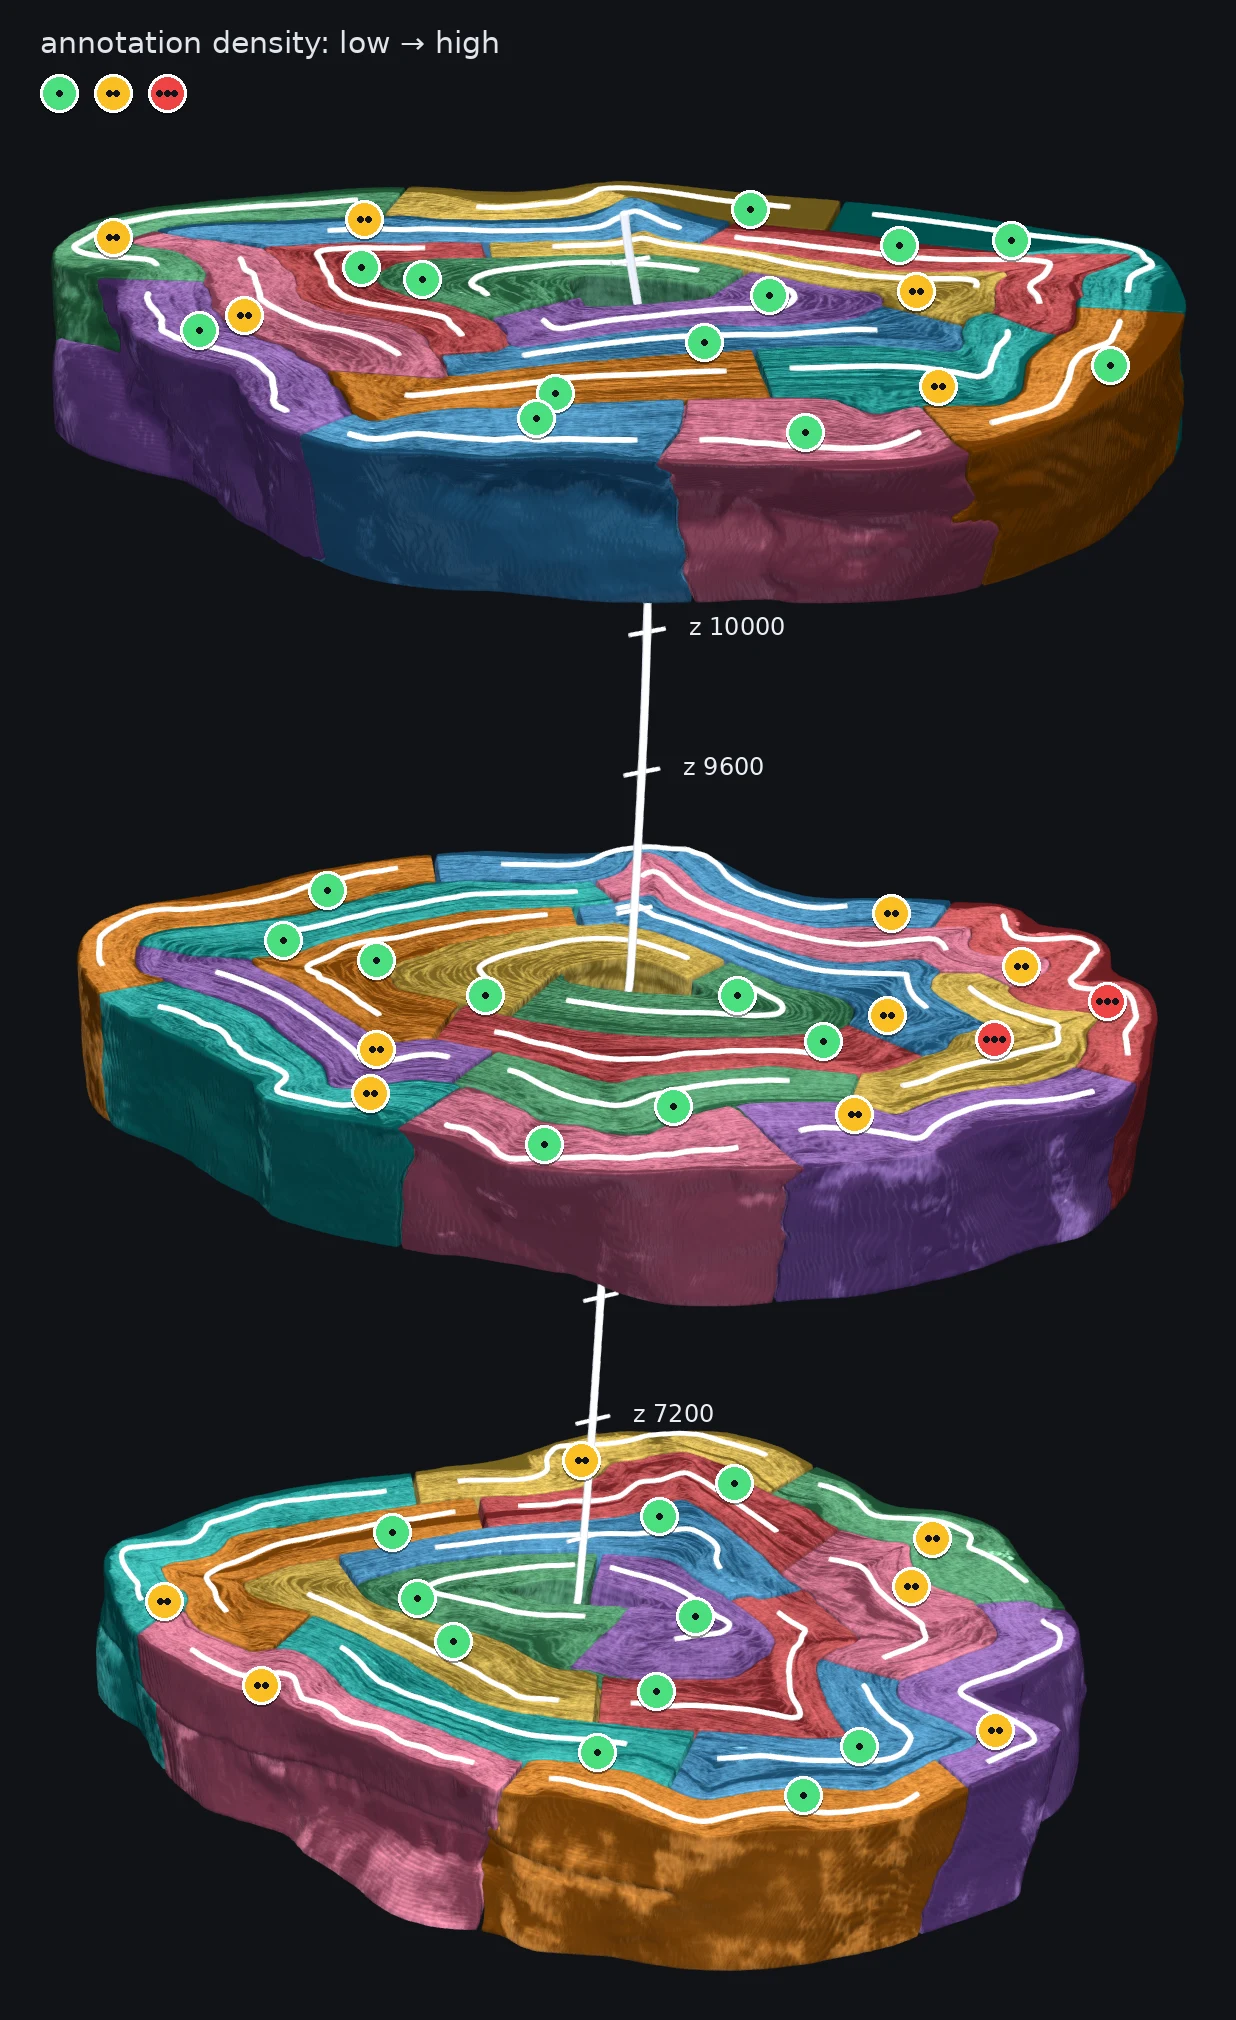
These "descriptions" typically come in the form of constraints like patches, fibers, or relative winding annotations. The "density" of these shape descriptors required in a given area depends greatly on how uniform the deformation is. If a large number of windings all make mostly the same shape, it could be very few. However if an area makes something more 3C than C (bear with me), you'll need a fair bit more annotation. The "complexity" of the local shape is the primary multiplier of annotation density, rather than the number of windings or the curvature alone. Once you've got a constraint that describes the neighborhood, there is little benefit in adding "more". You would not, for example, want to annotate multiple windings in a row radially if they are mostly the same shape and have somewhat regular spacing.
The other instance which typically requires more-than-usual amounts of annotation is the case of shears. In this context, a shear of the scroll is a location where the papyrus has not only broken apart but also shifted along an axis. These situations are particularly hard for a smooth field to interpolate (they are by nature unsmooth). In these types of areas it is best to try and find some portion of the scroll which you can follow through, and apply a fair bit of annotation on either side of the shear, as near as you can get to the actual missing papyrus.
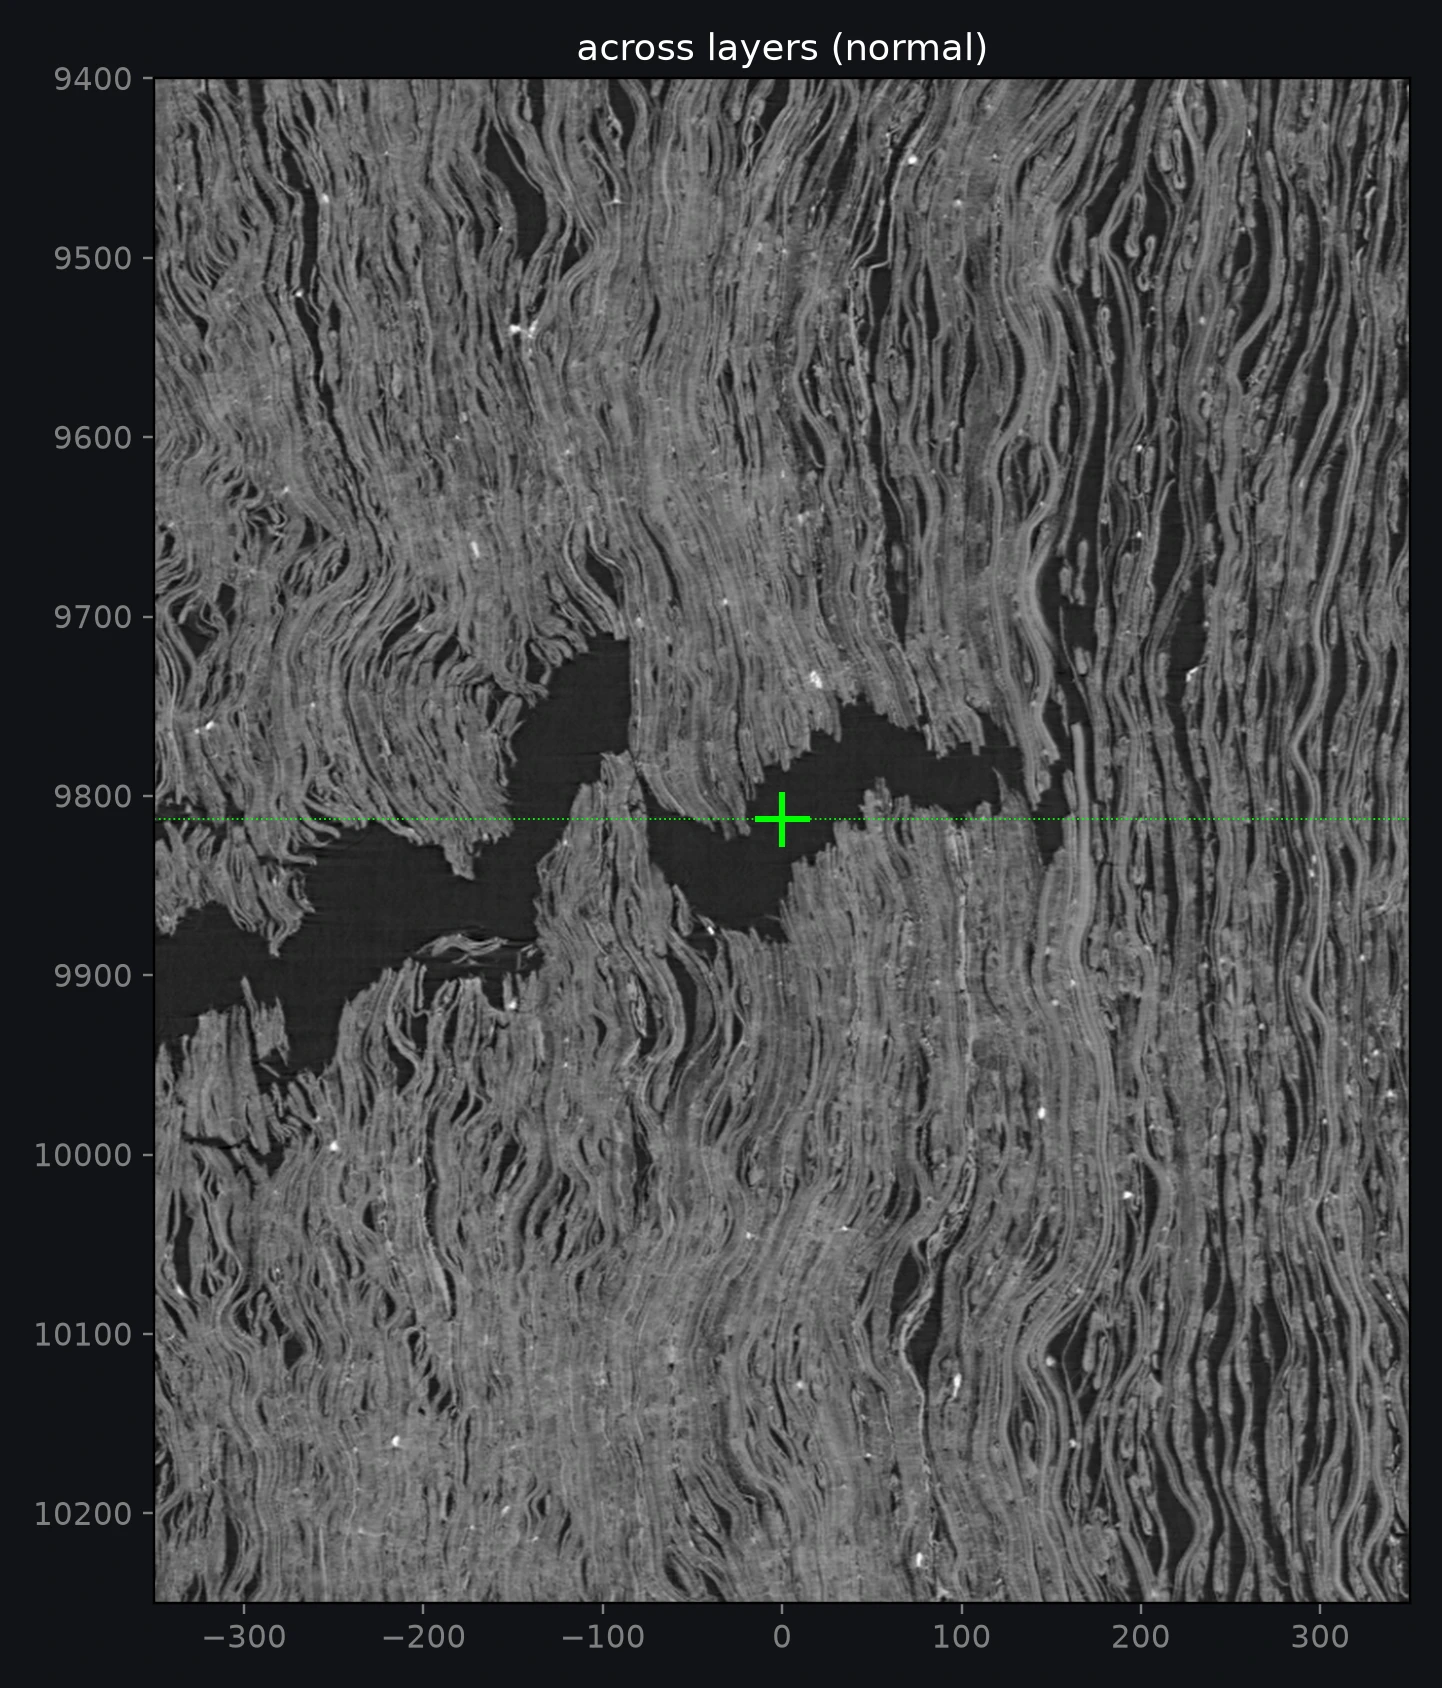
Now that we've described the bad areas, there are some shapes within a scroll which are "easier" (or at least as easy as unrolling an ancient carbonized scroll can reasonably be):
- Because the gap expander prefers to push outwards from its initial gap, and due to it being a cumulative sum of the gaps along the radial , the spiral will (for the most part) perform quite well in areas with regular spacing and curvature which happens smoothly over a large area. This reduces the amount of annotation we need in these areas
- Areas which have large gaps between windings that are sustained for long runs reduce the amount of "uncertainty" in the fit, and are typically fit well very early
- Areas with minimal curvature (even highly compressed ones)
Rendering ink
To get from per-winding meshes to readable images, use render_ink.py. It groups the _spliced winding meshes into winding-range chunks, concatenates each chunk into a single mesh (written to a concat/ folder — useful for loading the geometry behind each strip as one mesh), SLIM-flattens it, renders it through an ink-prediction volume with vc_render_tifxyz, and composites the result into one JPEG strip per chunk:
python render_ink.py /path/to/run/meshes/mesh --volume /path/to/ink_prediction.zarr
You'll need a VC3D build on your PATH for the rendering and flattening binaries (vc_render_tifxyz, flatboi, …), and an ink-prediction zarr for the scroll. The output ink/ folder fills with strips named by winding range (e.g. w010-027.jpg).
Ink metrics
The script get_ink_metrics.py computes some metrics based on the amount of letter-like ink signal detected in the ink renders. By default it uses the model scrollprize/ink-coverage-32um from HuggingFace; this is a 2D nnUNet operating on small patches, trained to do binary segmentation of clearly-identifiable ink. The script measures the total area of ink detected, as well as evaluating whether columns are coherent and have approximately the expected width, and lines are locally coherent (based on sliding windows) and have approximately the expected pitch.
The ink-coverage model was only trained on PHerc. Paris 4, so it may not give accurate results for other scrolls with significantly different writing styles.
How it works
Up to this point we treated the fit as a black box; here is what is actually inside it. (There are more math details in the paper Virtually Unrolling the Herculaneum Papyri by Diffeomorphic Spiral Fitting, though for a slightly older version of the algorithm.)
An ideal scroll...
Originally, a scroll was one nearly rectangular sheet of papyrus, rolled up (often around a central rod). In cross-section that is a spiral — specifically, we model it as a perfect archimedean spiral, extruded into the plane. Treating it as arbitrarily large, the ideal scroll has just one free parameter: the tightness of its windings, . A point on the ideal sheet is addressed by two curvilinear coordinates — the angle along the spiral and the height along the axis — and sits at radius
so each full turn moves the sheet outward by one sheet-to-sheet spacing . Plug in any and you get a 3D point on the ideal sheet.
...horribly deformed
The eruption turned that neat spiral into the crumpled shape in the scan. We model the damage as a diffeomorphic transformation: a smooth, differentiable, invertible map of 3D space. That choice buys us exactly the guarantees we need:
- It cannot tear the sheet, make it pass through itself, or squish it to a point — it preserves topology. If it starts as a spiral, after deformation it is still a spiral, just a messed-up one.
- It is invertible: a point on the ideal scroll maps to a point in the scan, and — just as importantly — any point in the scan maps back to a point on the ideal (i.e. flattened) scroll. That inverse map is the virtual unrolling.
The deformation is composed of three parts applied in sequence: a coarse global scale and shear, the integral of a stationary velocity field (the most important one), and a local scaling of the gap between windings, defined everywhere on the sheet (this lets windings locally squeeze together or spread apart without disturbing anything else). Each part is smooth and invertible, so the composition is too.
The middle term deserves a closer look. Imagine a little 3D arrow attached to every point in space — a velocity field . Every point of the ideal spiral flows along these arrows, like dust in a (smooth, steady) wind. Mathematically, the trajectory of a point is defined by the ODE
and the transformation is where the flow ends up after one unit of time: . Don't worry too much about the equation — the intuition is what matters: every point rides smoothly along the flow, so the whole spiral deforms smoothly into a new shape, and running the flow backwards gives the exact inverse. This is the same machinery used in diffeomorphic medical image registration; in the code, the ODE is integrated with a few Runge–Kutta steps (flow_fields.py, transforms.py).
Fitting as an inverse problem
Fitting is then an inverse problem: find the winding tightness and the deformation parameters (the velocity field, plus the scaling terms) such that the deformed spiral explains what we see in the scan. We don't fit to the raw CT intensities directly. Instead, every input from What goes in becomes a differentiable loss term saying what the deformed spiral should look like:
- points from a same-sheet strip should all land on some winding surface (and the same one);
- two points annotated as windings apart should land exactly windings apart;
- a verified patch should coincide with a single winding across its whole extent;
- tracks, normals, and gradient-magnitude volumes nudge the surface orientation and winding density;
- the innermost winding should wrap the umbilicus, and the outermost should follow the outer shell;
- and regularization terms keep the sheet parameterization from distorting.
All parameters are optimized jointly, with plain Adam, minimizing the weighted sum of these losses (the weights are the loss_weight_* entries in default_config). In effect, we tell the machine "here are all the constraints humans and models have gathered — find the deformation that squishes the ideal spiral so that they are all met", and gradient descent does the rest.
At the end, we sample each winding of the fitted ideal spiral on a regular grid, push the samples through the fitted deformation into scan coordinates, and write each winding out as a tifxyz mesh — the outputs described above.
One caveat when reading the paper: it describes a fully automatic setup that fits only raw surface-prediction tracks and fields derived from them. The current code fits the much richer curated evidence described in this tutorial — verified patches, fibers, and winding annotations — which is what makes it accurate enough to target whole-scroll segmentation. The underlying model and optimization are still very similar.
Footnotes
-
The surface tracer is an earlier attempt at this problem: it stitches overlapping patches into large segments automatically. But it requires the patches to physically overlap or touch, and it becomes unreliable at whole-scroll scale. ↩